Built for real workflows
Machine Learning teams
Feed agents and RAG pipelines with LLM-optimized Markdown while trimming token costs by up to 80%.
SEO Agencies
Generate readability reports and content audits in seconds. Export clean text for keyword analysis without manual copy-paste.
Newsletter Tools
Auto-curate and summarize articles from RSS feeds. Turn any URL into formatted Markdown ready for your email templates.
UX Teams
Add instant reader-mode embeds to your app. Deliver distraction-free reading experiences without building your own parser.
LLM pipelines, ready out of the box
- Return deterministic Markdown + JSON fields (`stats.wordCount`, `readableApplied`) so you can chunk, embed, and cite without extra parsing.
- Token-aware trimming removes nav/ads before the data hits OpenAI, Anthropic, or Gemini—perfect for agent tool calls.
- Drop-in snippets for LangChain, LlamaIndex, and vertex embeddings make it easy to hydrate your vector store.
Starter example: call HTMLExtractor API inside a LangChain loader, persist Markdown + metadata to Pinecone, and keep the original HTML for audit trails.
Agency-grade content intelligence
- Batch fetch competitor URLs, then pipe Markdown into your readability or TF‑IDF scripts without manual cleanup.
- Generate per-page metadata (word count, headings, reading time) to power client-facing audits.
- Use the optional `includeOriginal` flag to preserve HTML for side-by-side comparisons in client decks.
Popular stack: Airtable (URL list) → HTMLExtractor API → Google Sheets / Looker Studio dashboards.
Newsletter automation
- Trigger HTMLExtractor API from RSS or Zapier, receive Markdown ready to paste into ConvertKit, Beehiiv, or Ghost.
- Attach stats like reading time and hero images to enrich your curated summaries.
- Pair with OpenAI summaries to ship daily digests without copy/paste fatigue.
Tip: bundle multiple extracted stories into a single JSON payload and let your template engine loop through each entry.
Reader-mode embeds for UX teams
- Embed distraction-free articles inside your app, knowledge base, or customer portal with a single fetch.
- Serve localized reader views from the edge while HTMLExtractor handles anti-bot and DOM cleanup.
- Use the structured JSON to style hero images, quotes, or code blocks natively in your UI.
Many teams pair HTMLExtractor with Next.js and edge functions to render clean previews inside product tours.
Automate it
- Zapier: Airtable URL queue → HTMLExtractor → Slack/Sheets updates.
- n8n: RSS trigger → HTMLExtractor → Beehiiv / ConvertKit campaigns.
- Edge workers: Notion DB → HTMLExtractor → Claude/Vertex summaries.
Works with Zapier, Make, n8n, LangChain, LlamaIndex, and serverless runtimes.
Paste a URL — see the Markdown
Paste any public URL below to watch HTMLExtractor strip nav, ads, and boilerplate in seconds. No API key required for the sandbox.
Show API request & response
curl -X POST https://api.htmlextractor.com/v1/extract \
  -H "Authorization: Bearer YOUR_KEY" \
  -H "Content-Type: application/json" \
  -d '{"url":"https://example.com","output":"markdown"}'
{ "success": true, "data": "# Clean Markdown..." }
Why teams choose HTMLExtractor
Ship faster
Stand up a production-ready extractor in <24h while we handle proxy rotation, JavaScript rendering, and parse fixes.
Any format you need
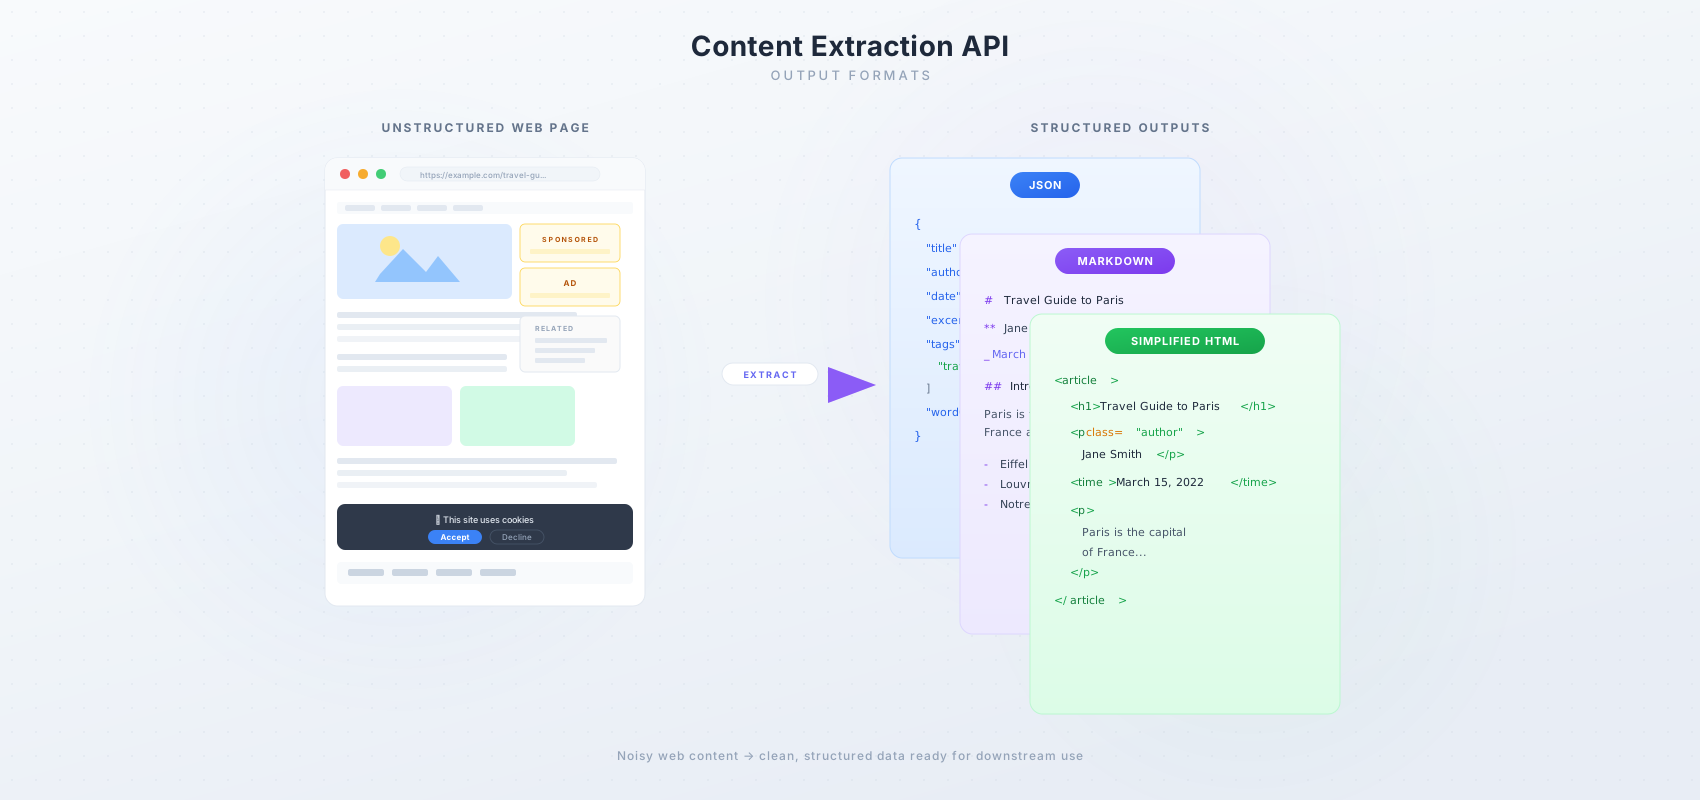
Markdown, JSON, HTML, or combined output with metadata like stats.wordCount plus readableApplied for audit trails.
Trust the data
99.95% uptime SLA, privacy-first architecture, and optional original HTML payloads for compliance or QA teams.
Scale globally
Global edge renderers keep round-trips under 200 ms worldwide so you can batch thousands of URLs without queuing.
Real-world transformations
Endpoint
POST https://your-worker.workers.dev/extract-content
Headers: Authorization: Bearer <token>, Content-Type: application/json
Request parameters
url or html
Provide a URL to fetch or raw HTML string. Set baseUrl when using HTML to resolve links.
output
html, markdown, json, or jsonmd (returns both HTML and Markdown fields).
readable
Boolean toggle to force reader-mode extraction even on already clean HTML.
includeOriginal
When true and output=json, response includes originalHtml for auditing.
Response snippets
Common integration recipes
Newsletter Summarizer
Fetch RSS feeds, extract clean Markdown from each article URL, send to OpenAI for summarization, compile into email template.
Stack: Node.js + RSS Parser + HTMLExtractor API + GPT-4
Knowledge Base Generator
Crawl documentation sites, extract structured content, index in vector DB, power internal search with semantic embeddings.
Stack: Puppeteer + HTMLExtractor API + Pinecone + LangChain
SEO Content Auditor
Bulk extract competitor pages, analyze word count and readability stats, export comparison reports for agency clients.
Stack: Python + HTMLExtractor API + Pandas + Tableau
AI Context Trimmer
Strip ads and nav from web sources before feeding to Claude/GPT, reduce token costs by 80%, improve accuracy on long articles.
Stack: TypeScript + HTMLExtractor API + Anthropic SDK
Transparent pricing
Basic
$0/mo
5,000 requests / month
- All output formats (MD + JSON)
- Global edge delivery
- Reader-mode + stats fields
- Community support
Pro
$10/mo
100,000 requests / month
- Everything in Basic
- Overage at $0.00003 / request
- Priority support
- 99.95% uptime SLA
- Usage analytics
Ultra
$25/mo
500,000 requests / month
- Everything in Pro
- Overage at $0.00003 / request
- Dedicated support
- Custom SLAs
- Highest throughput
All plans include Markdown, JSON, and HTML output with reader-mode extraction and content stats. Overage billed at $0.00003 per request on paid plans.
Trusted by teams building the future
Join AI startups, SEO agencies, and SaaS companies using HTMLExtractor to ship faster.